A precise-looking value may come from a manufacturer statement, preset, software check, contributor observation, physical measurement, or model prediction. Each can help with a different decision. Evaluate the claim that was made and the action you are considering; do not turn source authority, a complete form, or a community label into proof of a physical outcome.
Keep five evidence questions separate
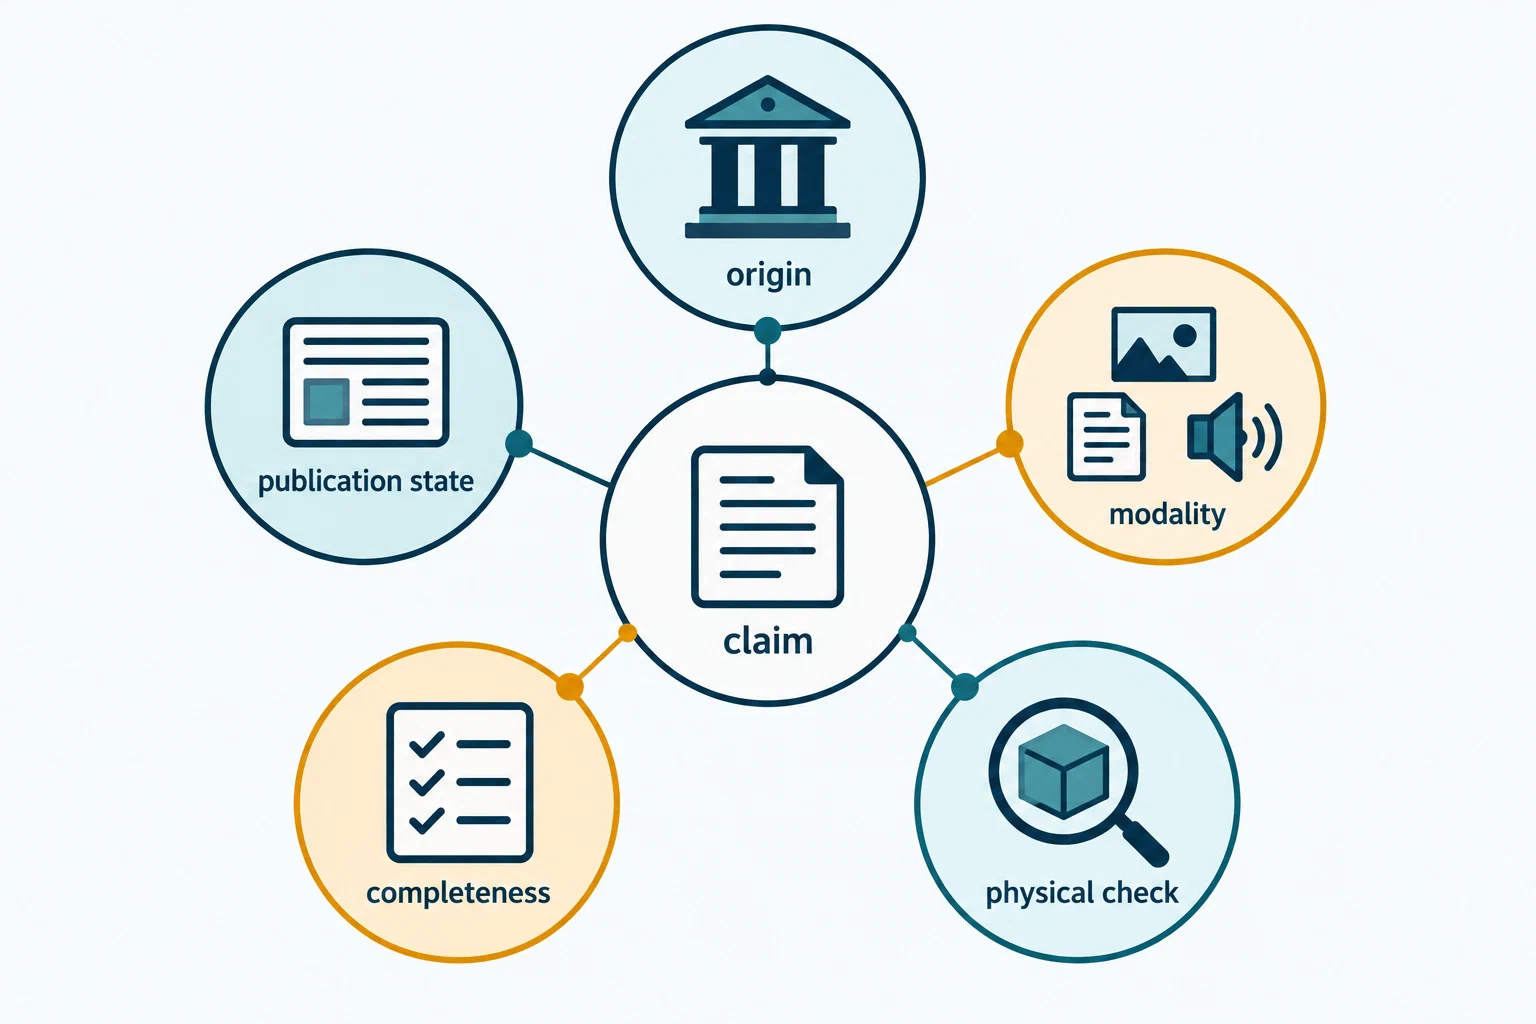
| Question | Examples | What to keep visible |
|---|---|---|
| Where did the information come from? | Manufacturer, slicer documentation, test lab, individual contributor, platform summary | Source and scope; an authoritative source still may not test this claim |
| What kind of evidence is it? | Preset value, file check, written observation, photo, sensor output, measurement, model prediction | Modality and the exact quantity or event represented |
| Was a physical result checked? | No print described, a reported print, an inspected specimen, a measured feature | Who checked what, on which setup, with which method |
| How complete is the record? | Exact printer and release known, partial context, missing method, unknown follow-up | Which comparisons the missing fields prevent |
| What is its publication state? | Current, corrected, superseded, withdrawn, moderated, or unavailable | Record lifecycle separately from technical validity |
These axes do not combine into one supported confidence score. A well-documented manufacturer capability is strong evidence that the maker states a feature is supported under its stated conditions; it is not evidence that a modified machine or shared profile was tested. A profile validator can show that its defined software checks passed; it cannot show that a physical printer produced an acceptable part.
Classify the claim at the level it supports
- Capability or product guidance: identifies a documented feature, limit, or recommended starting point. It does not establish performance of a modified setup.
- Preset or saved configuration: shows that a named value or relationship exists. It does not show that the value is optimal, portable, or physically tested.
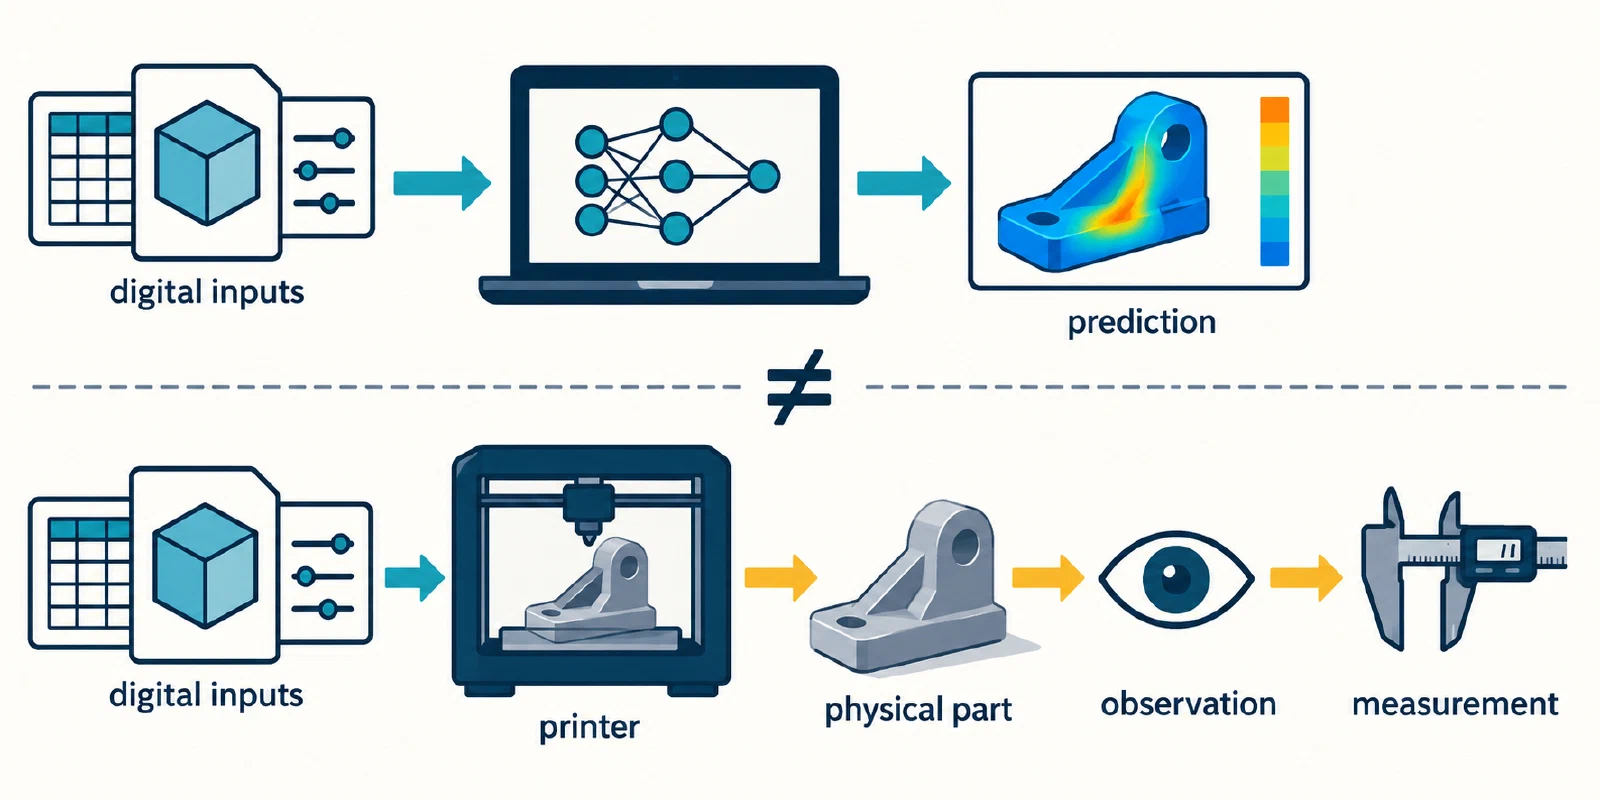
- Software check: shows that a file opened, a rule passed, or a preview contained an expected field. It is not a physical result.
- Reported observation: records what a named contributor says happened on a described setup. Missing procedure or context limits reproduction.
- Measured result: needs a stated quantity, units, object or feature, method, setup, and comparator. Preserve sample count and spread when supplied.
- Prediction or interpretation: shows a model output or conclusion derived from other evidence. Keep the prediction or reasoning identifiable; do not relabel it as an observed print.
- Unknown or conflicting: leaves a missing field, disagreement, or unverified explanation visible until a relevant check resolves it.
For measurements, use the terminology precisely. NIST describes repeatability for measurements made under the same measurement conditions and reproducibility when conditions change; name the conditions that changed. Repeating several measurements on one object or printer is not by itself evidence that another setup will reproduce the result. NIST’s historical additive-manufacturing pilot reported relatively consistent geometric results within individual tested printers but substantial variation between printers, and identified build pedigree as important to investigating causes. That bounded pilot does not represent every current consumer printer.
Predicted labels also need their source boundary. A preprint that ranked possible printability issues from STL geometry states that its training models were not physically printed and tested. Those model outputs and any user-label comparison are prediction evidence, not observed print outcomes.
Distinguish a report, a pattern, and scoped corroboration
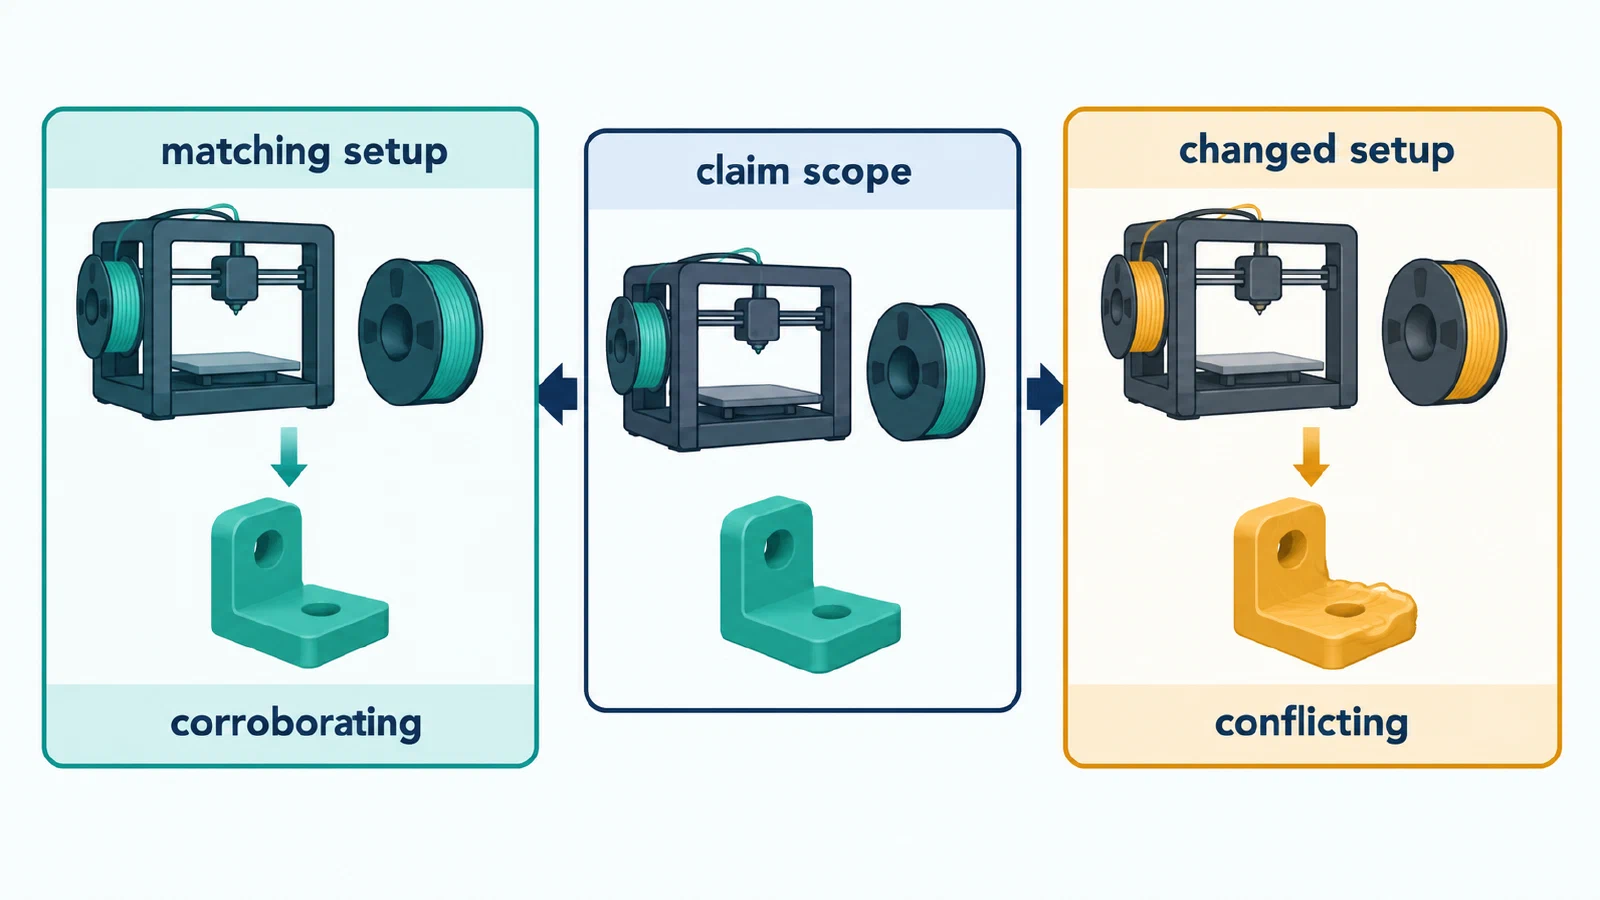
A single report is one contributor’s bounded account. A pattern is a descriptive recurrence across records that meet the stated eligibility rules; it should retain counterexamples, missing context, and whether records come from independent setups or repeated runs on one setup. Scoped corroboration requires documented relevant methods and separate setups that support the same named claim. None of these states has a universal report-count promotion rule. Votes, agreement, or a complete intake form cannot replace the physical check the claim requires.
After submission, name any check performed and its reference or comparison basis. A moderation or completeness review can establish that required fields or community rules were checked; it does not establish that the reported part was physically tested. Subjective ratings, platform confirmations, publisher-defined scores, raw measurement rows, and physical outcomes should remain separate fields.
Inspect summaries, scores, and missingness
Ask what a publisher counts as a record, a completed test, a rating, a measurement, and an available score. A dated public material catalog snapshot, for example, reported 267 included records, with 145 complete across its three rigid-test modules, 105 partial, and 17 without rigid-test results. It reported availability counts for native measurements and scores separately. Those are catalog coverage states in that snapshot, not a representative sample of consumer prints or evidence that a material suits another machine.
A publisher’s score or confidence field also needs its own definition. One public material report presents an internal confidence indicator alongside measurements; its publisher says the indicator is not a 95% confidence interval, and describes the work as in-house equipment rather than accredited laboratory testing. Treat the field as that publisher’s output and keep its method, sample, and raw-data limits visible. Do not convert a score into engineering units or a formal statistical interval.
Use a claim ledger in prose or a table: claim; source; evidence type; exact setup and scope; procedure or measurement method; observed result; missing context; next check. Then choose an action proportionate to the evidence: read-only comparison, isolated import, a suitable first-layer or calibration check, a representative print, or no reuse until the identity is resolved. There is no universal report count that proves causality or makes a profile safe to copy.
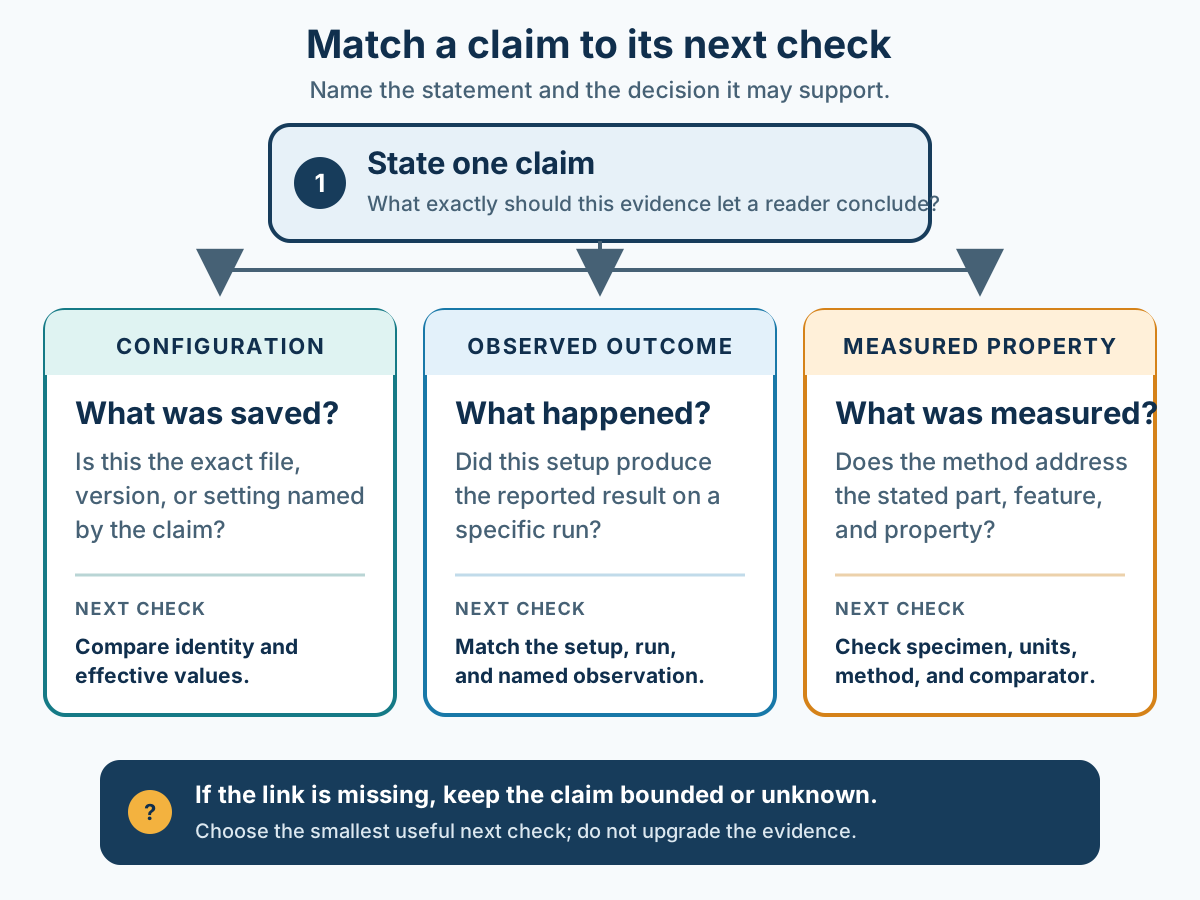
When several reports answer one question, use the aggregation guide . For the complete contributor record, see sharing a result with reproducible context ; use revision comparison when the claim concerns two versions.
Back to top ↑